


Why Protocol Teams Need a Knowledge Base First
This article is for clinical development leaders, medical writing heads, regulatory operations teams, and digital transformation owners evaluating ai protocol writing software. The core answer is simple: AI protocol writing becomes useful only when source knowledge is organized enough to be retrieved, scoped, and trusted.
Most sponsors already own the raw ingredients: legacy protocols, protocol synopses, product information, statistical analysis plans, schedules of activities, regulatory correspondence, and approved standard language. The problem is not absence. It is distance. Those materials sit in folders, document management systems, spreadsheets, and team memory.
An AI assistant can draft quickly, but without a protocol knowledge base it may draft from too little context, too much context, or the wrong context. That is where authoring teams lose the plot. Speed is exciting; source discipline is what makes speed usable.
What Belongs in a Protocol Knowledge Base
A protocol knowledge base should be narrow enough to govern and broad enough to reflect how teams actually write. A strong starting set includes at least 5 source categories:
| Source Category | Why It Matters | Governance Question |
|---|---|---|
| Prior protocols | Reuses proven study logic and language | Which studies are similar enough? |
| Protocol synopses | Carries the design spine of the study | Is the synopsis structured and current? |
| Product information | Grounds investigational product context | Which version is authoritative? |
| SAP or statistical inputs | Supports statistical sections and endpoints | What needs statistician confirmation? |
| Regulatory feedback | Captures authority expectations | Should it be read-only reference context? |
AuroraPrime RMA supports selecting related documents from the Document Library, such as a study design concept sheet or protocol synopsis, as references for generating an initial protocol draft. That matters because the author chooses the source set before generation begins, instead of letting AI roam across a broad repository.
How AuroraPrime RMA Turns References Into Drafting Context
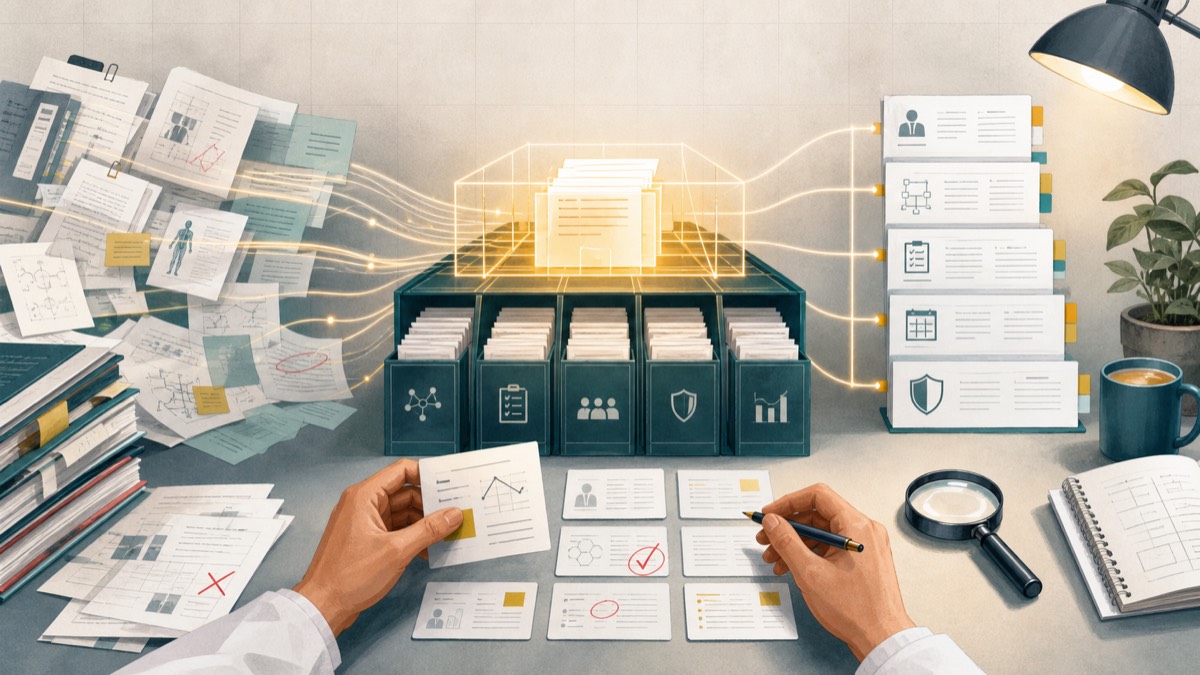
The important shift is from storage to authoring context. A protocol knowledge base should not simply hold files. It should feed the right source information into the right section at the right time.
AuroraPrime RMA generates content section by section and inserts it into corresponding locations in the selected protocol template. It also supports content generation rules that let Template Admins specify generation methods and information sources for individual sections. That is the difference between a generic repository and a governed authoring system.
For messy source documents, the system can use Information Element AI Extraction, where the add-in reads the source document and extracts content based on the user's input rather than requiring an exact source heading. For cleaner source documents, Section Name Match can retrieve a specified section by name. In practice, teams need both. Legacy source packs are rarely tidy all the way through.
The payoff is not just faster drafting. It is fewer blind spots. If a study design changes, a prior protocol is superseded, or a source package is incomplete, the knowledge base should expose the problem early, before a writer spends 3 days polishing unsupported text.
A Practical Checklist for Sponsors and CROs
Before scaling pharma r&d document automation solution projects for protocol authoring, ask 8 questions:
Which protocol types and phases are in scope for the first release?
Which prior studies can be reused, and which must be excluded?
Which metadata labels matter: therapeutic area, indication, phase, region, product, study design, endpoint type, or template family?
Which source documents are authoritative when two references disagree?
Which sections require mandatory inputs before generation?
Which sections should summarize, copy, transform, or generate new text?
Which source evidence must remain visible to reviewers?
Which gaps should become explicit placeholders instead of plausible prose?
That last question is easy to underestimate. A knowledge base should not make unsupported drafting more fluent. It should make unsupported drafting harder to miss.
Frequently Asked Questions
What is a protocol knowledge base?
A protocol knowledge base is a governed collection of prior protocols, synopses, study inputs, regulatory references, and approved writing examples that can be retrieved and applied during protocol drafting.
Why is a protocol knowledge base important for AI writing?
AI protocol writing depends on context. A knowledge base helps define which sources may be used, how content is retrieved, and how generated text can be traced back to evidence.
Can AI use protocol synopses as structured inputs?
Yes. AuroraPrime RMA can use a protocol synopsis or study design concept sheet as a reference for initial protocol draft generation.
Should regulatory feedback be part of the knowledge base?
Often, yes, but with controls. Regulatory feedback can be treated as read-only reference context, with human review deciding how it affects protocol language.
What is the risk of skipping knowledge-base governance?
Teams may generate fluent text from stale, irrelevant, or conflicting references. That creates downstream review burden and can weaken confidence in AI-assisted authoring.
Conclusion
The next wave of ai writing platform for life sciences adoption will be less about who can generate paragraphs and more about who can govern context. Protocols are too interconnected for blank-box drafting.
AuroraPrime RMA points to a better pattern: start with controlled templates, selected related documents, configurable source rules, and section-level generation. Then let writers work from a knowledge base that has been shaped for the document, not merely uploaded somewhere nearby.
To explore governed protocol knowledge bases for AI-assisted authoring, contact AlphaLife Sciences at https://alphalifesci.com/contact-us.
